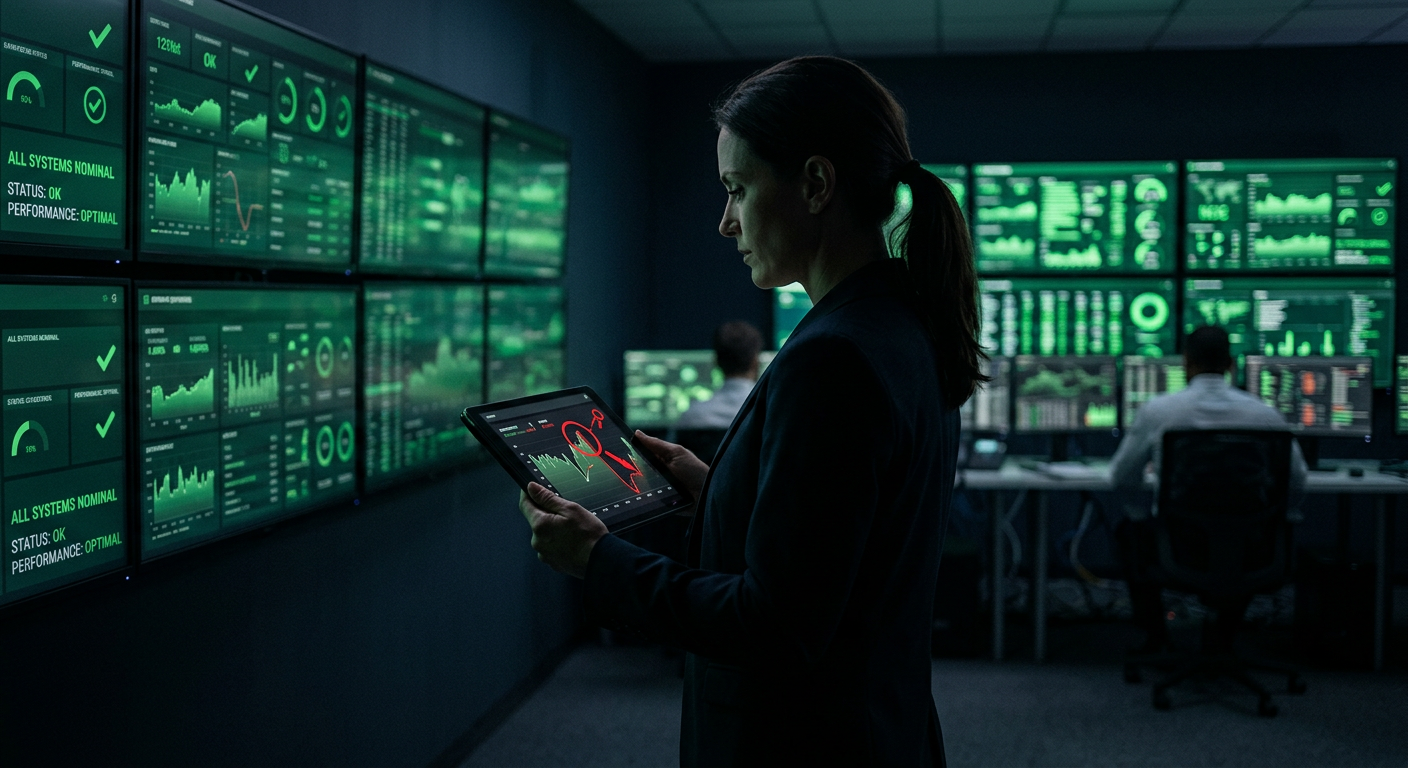
Every enterprise dashboard tells the same reassuring story: systems green, uptime nominal, compliance checked. Boards read that story and conclude the enterprise is safe. It isn't a lie. It's an incomplete measurement being mistaken for a complete one.
A dashboard measures whether a system is running. It says nothing about whether the decisions running through that system are the right ones — or whether anyone could produce evidence for them if a regulator, an auditor, or a crisis asked tomorrow. Green means available. It has never meant governed.
That gap is where I've spent thirty years working, first inside enterprise architecture practices at IBM, Oracle, and Fortune 500 institutions, and now designing the governance layer that AI-augmented enterprises still don't have: a way to test not just whether a system works, but whether the decisions behind it survive contact with someone actively trying to break them.
The Question Every Framework Asks, and Few Enterprises Can Answer
ISO 42001 and the EU AI Act both converge on the same underlying demand: not "is the AI accurate," but "can you show who authorized it to decide what, and what happens when that decision is wrong." That's an evidentiary standard, not a technical one. Most enterprises can produce architecture diagrams. Very few can produce a record of a decision being challenged, defended, and resolved before it ever reached a customer, a regulator, or a headline.
ARCHAI Enterprise AI SWAT™ was built to close exactly that gap. It is a controlled simulation environment — not a penetration test of infrastructure, but an adversarial test of enterprise assumptions — run through four distinct analytical perspectives rather than one consultant's opinion.
Four Perspectives, One Accountable Decision
- RED, the Evil Twin, is instructed to find the weakest assumption in the room and attack it — the dependency nobody documented, the customer segment quietly eroding, the process everyone assumes still works the way it did two years ago.
- BLUE, the Architect, has to respond with a structural answer, not a reassurance.
- GOLD, the Capitalist, prices the exposure and the opportunity in terms a CFO would recognize, not in the language of risk registers nobody reads.
- JUDGE renders the decision, on the record, with the evidence from all three perspectives attached.
The sequence runs through five governed stages: define the consequential question, lock the authorized enterprise context so the simulation never runs on unverified or unauthorized data, run the controlled missions, architect the response, and let leadership decide — in writing, with evidence, not with a slide that gets filed and forgotten.
Why This Belongs in a Governance Conversation, Not a Marketing One
The methodology produces exactly the artifact an auditor or a board risk committee asks for and rarely receives: a documented chain from question, to adversarial challenge, to architectural response, to an accountable human decision. That chain is the Decision Stack's governance layer made concrete — Policy Definition, Boundary Mapping, Accountability Chain, Audit Trail, Incident Protocol — not as a slide, but as the actual record of what happened.
A demonstration environment, run against a fictional company built specifically so no real client data is exposed, shows the mechanism working end to end before any enterprise has to commit its own context to it.
"Green systems will keep reporting themselves as safe. The only way to know if that's true is to put someone in the room whose job is to prove it wrong — and to keep the record of what happened when they tried."
Explore the methodology or request an executive session →
Tags: AI Governance, Enterprise Architecture, ISO 42001, EU AI Act, Adversarial Testing, Decision Intelligence, ARCHAI SWAT.